Γιώργος Κυριακαράκος
Administration Team
- 17 June 2006
- 11,969
Μόλις έγινε!Μήπως να κάνουμε ένα ξεχωριστό νήμα που να αφορά μόνο τα local μοντέλα; Νομίζω θα είχε ενδιαφέρον..
Αγαπητοί φίλοι και φίλες,
Σας προσκαλούμε να γιορτάσουμε μαζί τα 20α γενέθλια του AVclub.
Το Σάββατο 10 Οκτωβρίου, από τις 18:00 θα πραγματοποιήσουμε το πάρτι των γενεθλίων του φόρουμ μας στο Peñarrubia Lounge.
Δηλώστε τη συμμετοχή σας εδώ, θα χαρούμε πολύ να σας δούμε από κοντά.
Μόλις έγινε!Μήπως να κάνουμε ένα ξεχωριστό νήμα που να αφορά μόνο τα local μοντέλα; Νομίζω θα είχε ενδιαφέρον..
 openclaw.ai

 newsletter.semianalysis.com
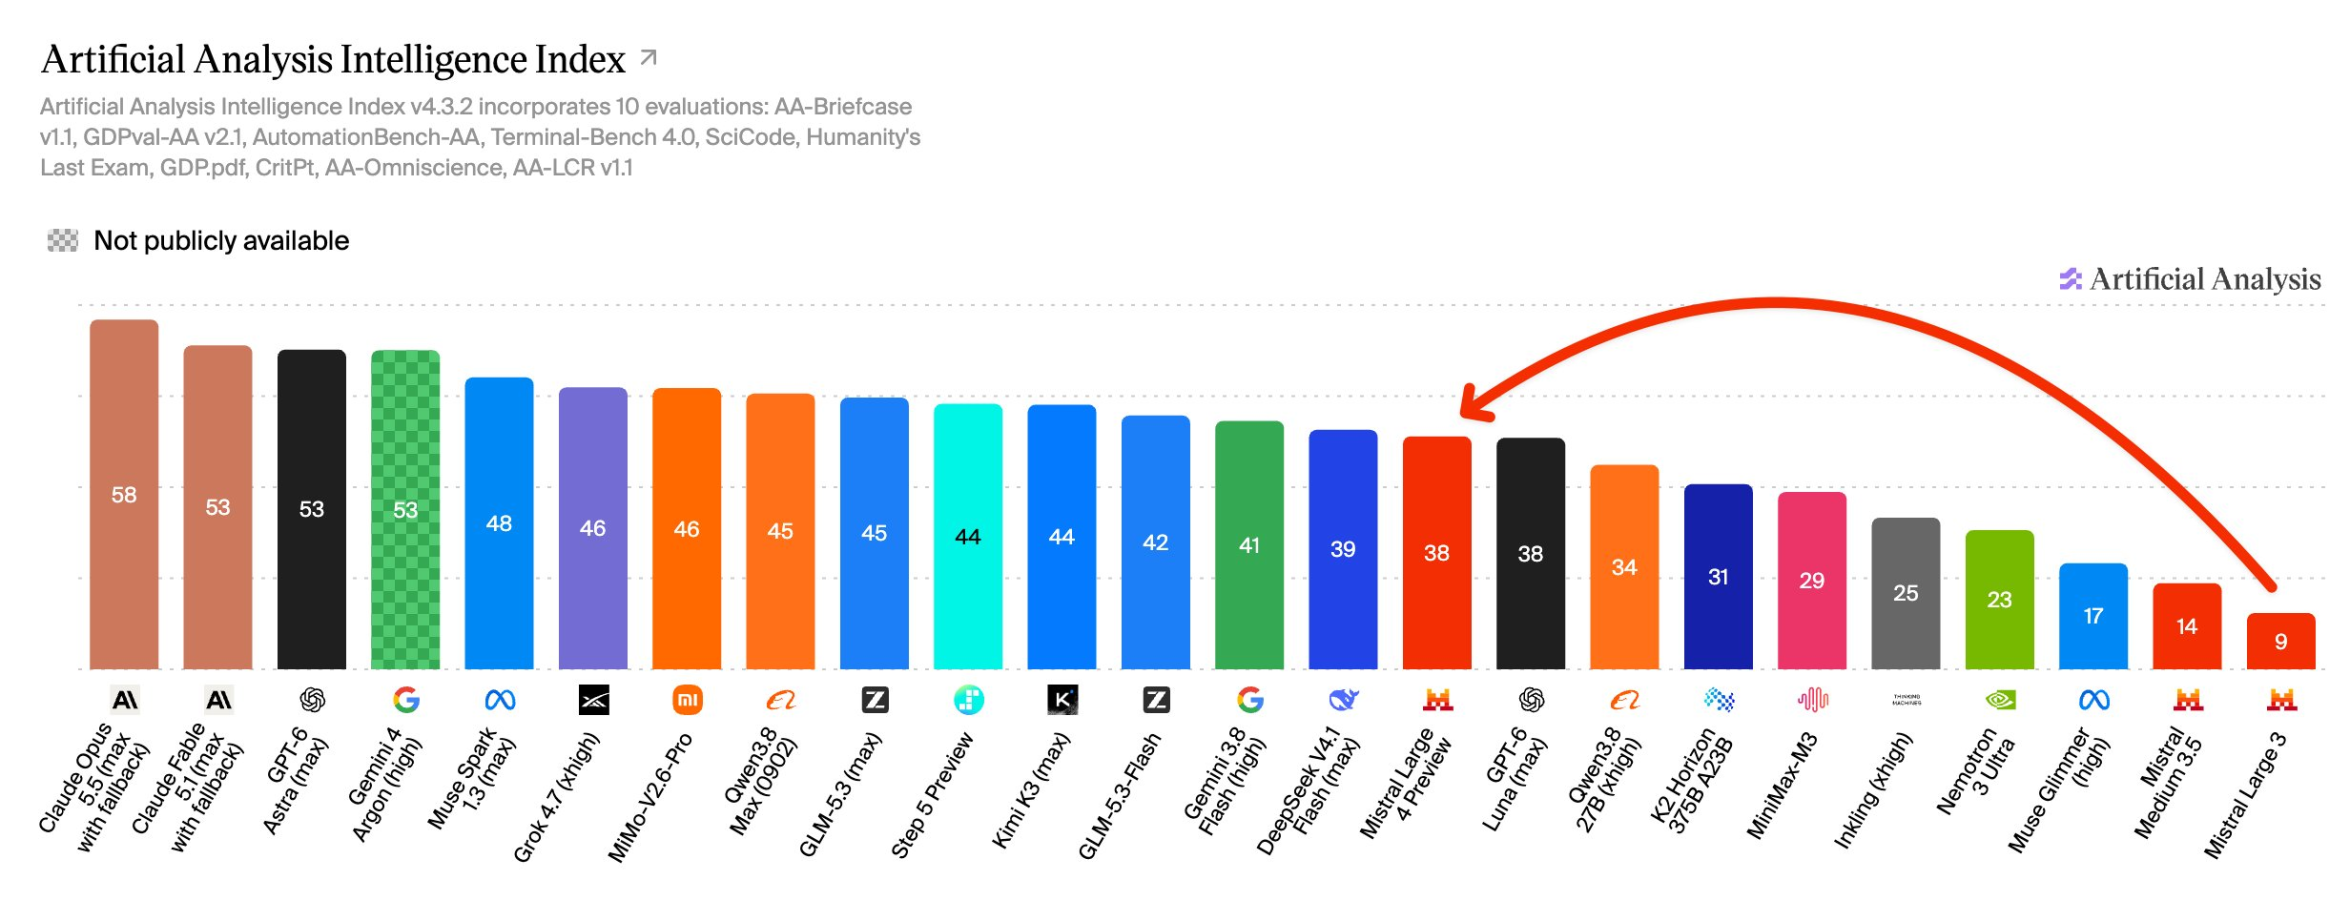
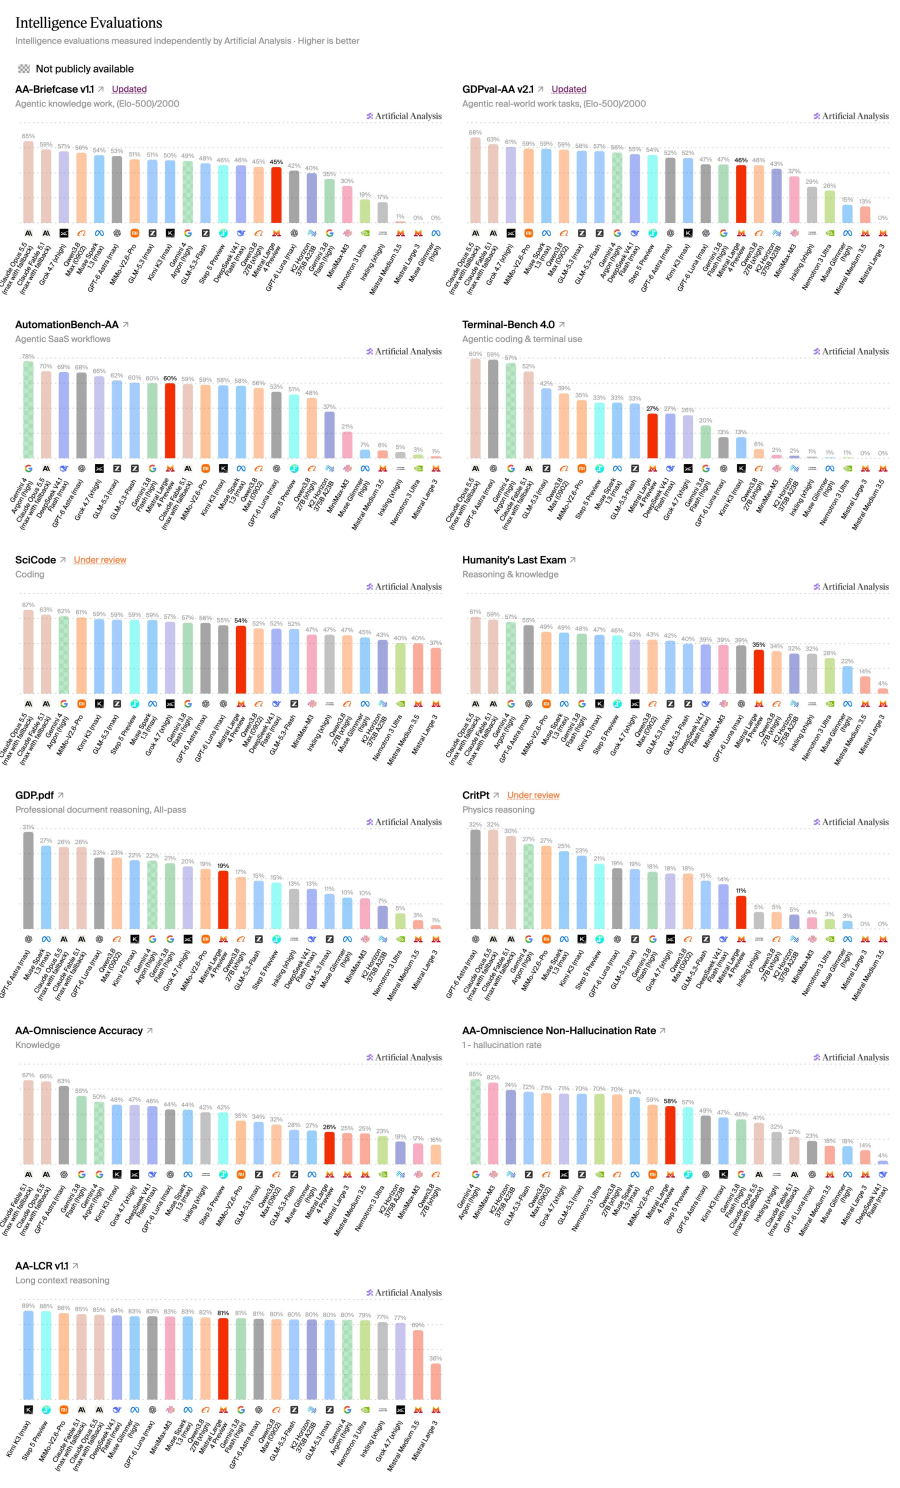
Mistral has released Mistral Large 4, scoring 38 on the Artificial Analysis Intelligence Index; France is back to having the most intelligent model from outside the US and China
@MistralAI
has released Mistral Large 4 in Research Public Preview, with plans to release the weights of the 1T parameter (49B active) model at the end of October. It achieves 38 on the Artificial Analysis Intelligence Index, comparable to GPT-6 Luna (max, 38) and DeepSeek V4.1 Flash (max, 39). It also achieves 50% on the Artificial Analysis Cyber Index, level with GLM-5.3-Flash and ahead of models such as Kimi K3 and DeepSeek V4.1 Flash (max).Key benchmarking results for Mistral Large 4 Preview:
➤ Most intelligent model from outside the US and China: Mistral Large 4 Preview scores 38 on the Intelligence Index, comparable to DeepSeek V4.1 Flash (max, 39) and GPT-6 Luna (max, 38). This makes it the most intelligent model from outside the US and China, ahead of countries such as South Korea and the United Arab Emirates
➤ Level with GLM-5.3-Flash on cyber defense capability: Mistral Large 4 Preview scores 50 on the Artificial Analysis Cyber Index, level with GLM-5.3-Flash (50) and behind MiMo-V2.6-Pro (56). Once its weights are released, it will rank among the top three open weights models on the Cyber Index. Its strongest result is on CyberGym-E2E-AA, where it scores 82%, ahead of MiMo-V2.6-Pro (79%) and GPT-6 Luna (max, 78%)
➤ Over 4x the Cost per Task of similar-intelligence open weights models: Mistral Large 4 Preview costs $1.13 per Intelligence Index task with standard pricing of $1.36/$4.18 per 1M input/output tokens, with $0.14 per 1M cached input tokens. For the first two weeks, Mistral Large 4 Preview will be served at a 50% launch discount, bringing its Cost per Task down to $0.57. This is still more costly than GLM-5.3-Flash ($0.25) and DeepSeek V4.1 Flash (max, $0.27)
➤ Strong document and image reasoning: Mistral Large 4 Preview scores 19% on GDP.pdf, on par with MiMo-V2.6-Pro (19%) and behind Kimi K3 (22%). This is an 18-point improvement from Mistral Large 3, partly driven by improvements in their API, which now accepts 100 images per request, up from 8 for previous Mistral modelsKey model details:
➤ Context Window: 512k tokens
➤ Multimodality: Text and image input, with text output
➤ Pricing: $1.36/$4.18 per 1M input/output tokens ($0.14 per 1M cached input tokens), with 50% off for the first two weeks ($0.68/$2.09
➤ Availability: Research Public Preview on Mistral's API, with open weights planned for the end of October
Κανένα μικρό να δούμε αν θα βγάλουν. Το προηγούμενο δεν κατάφερα καν να το κάνω να τρέξειΝέο μεγάλο μοντέλο από την Ευρωπαϊκή Mistral -η οποία είχε χαθεί.
View attachment 278664
Σημειώστε πως εκπαιδεύτηκε σε 4000 Nvidia Blackwell GPUs, ενώ το GPT-6 Astra σε 100.000
Αναλογικά με την υποδομή που είχαν, έκαναν μια χαρά δουλειά.
Για να έχουμε μια τάξη μεγέθους, στα Benchmarks είναι στο επίπεδο του GPT 5.4 το οποίο πριν από λίγους μήνες ήταν frontier.
Όλα τα benchmarks:

 github.com
Θα βάλουμε αλλα AI να το κάνουν, και η πλάκα θα είναι οταν αρχίσουν να βρισκουν ευρήματα η άλλο δικο τους τρόπο επίλυσης πιο γρήγορο-έξυπνο (αρα περισσότερες λύσεις του ενος εντέλει)Υ.Γ. Το μεγάλο πρόβλημα είναι ότι δεν έχουμε αρκετούς ανθρώπους με το κατάλληλο υπόβαθρο για να ελέγξουν μέσω peer-review τα άρθρα αυτά σύντομα...
Αυτό το έχει κάνει ήδη η OpenAI πριν καταθέσει τα paper. Σχεδόν όλα έχουν τις λύσεις σε γλώσσα LEAN που είναι αυτή που χρησιμοποιούν οι μαθηματικοί για να ελέγχουν τέτοια θέματα.Θα βάλουμε αλλα AI να το κάνουν, ...

 www.anthropic.com
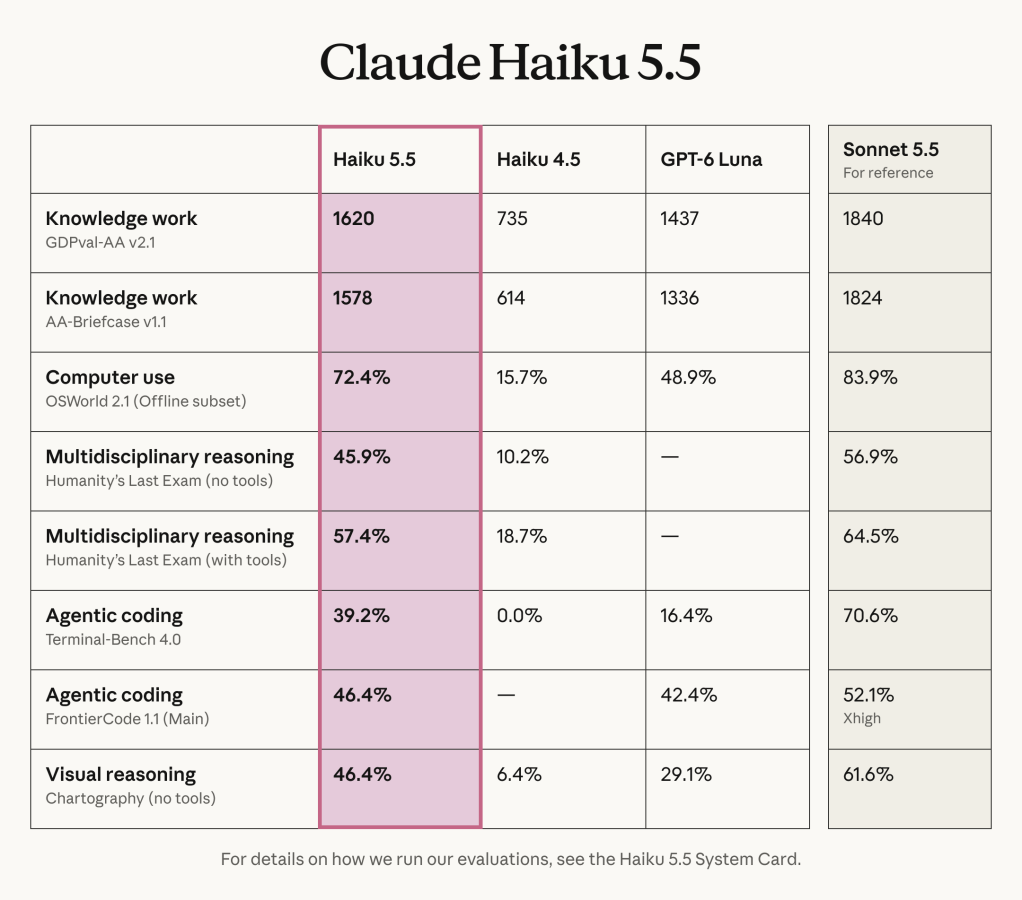
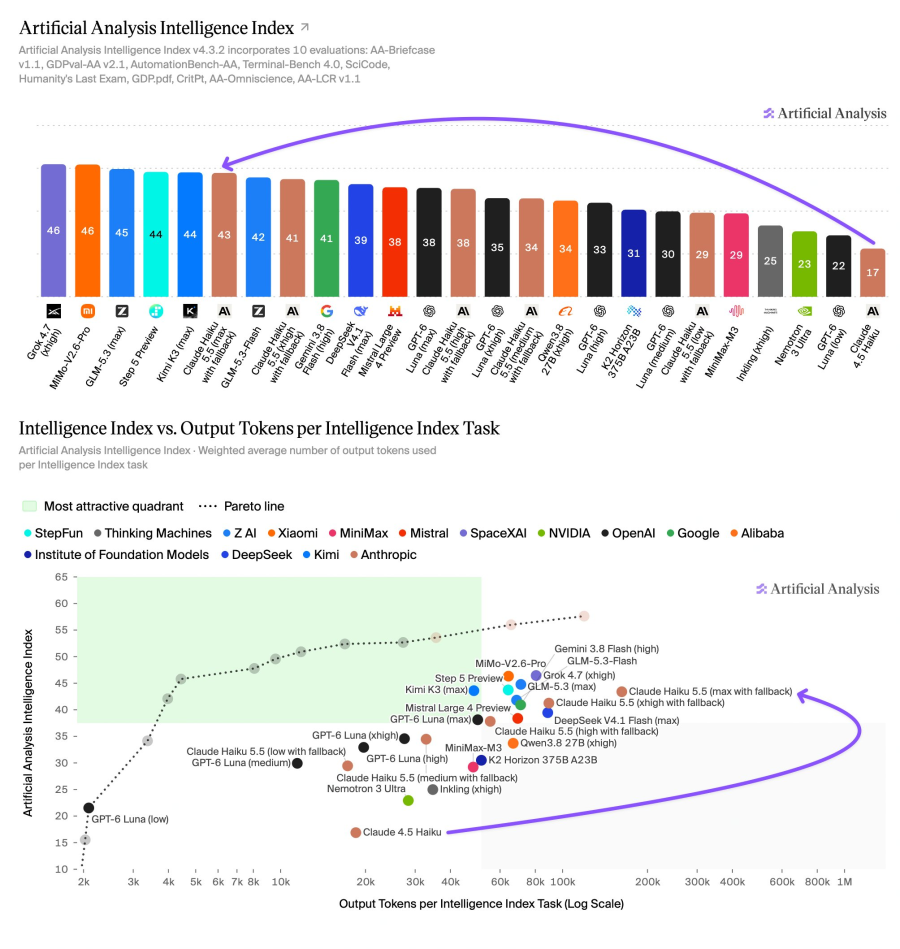
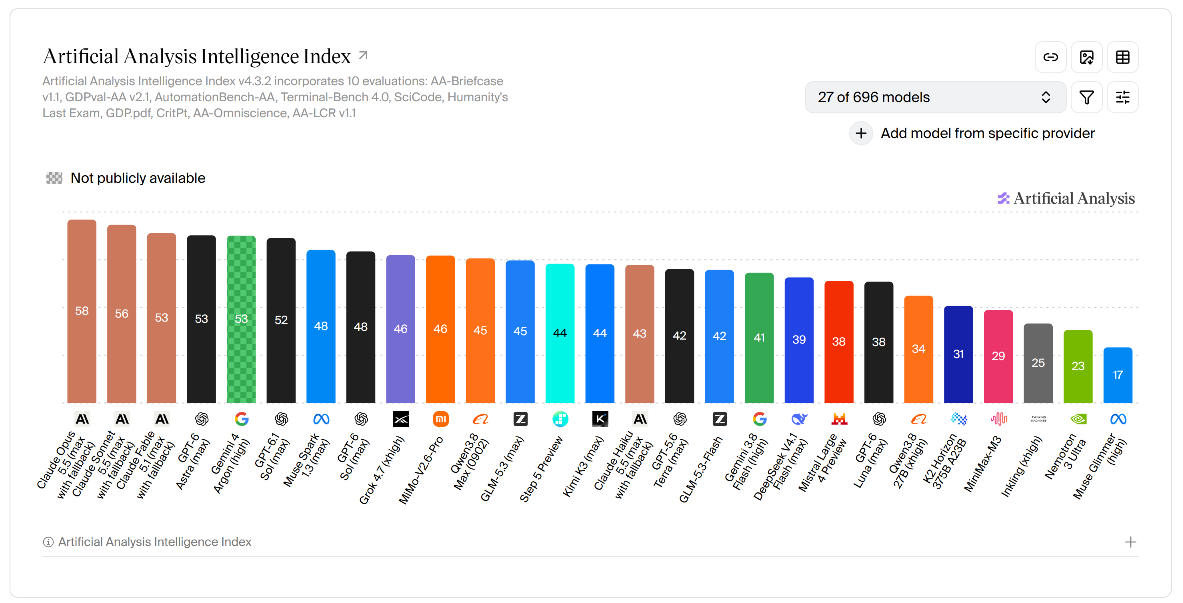
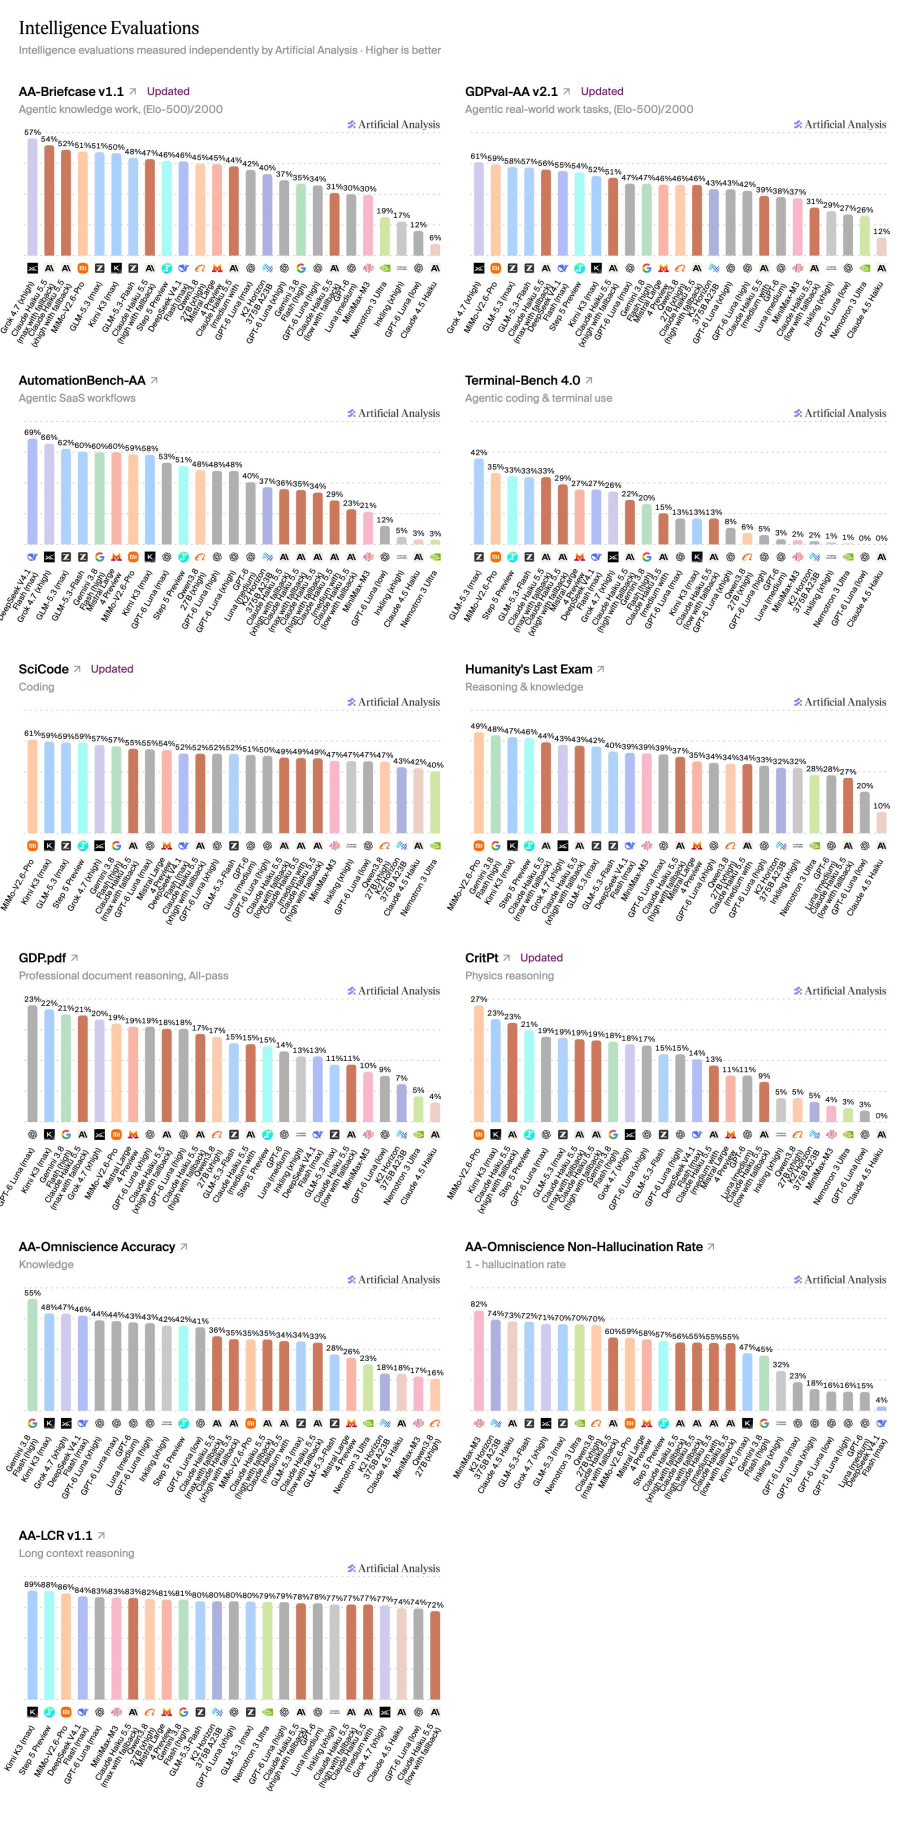
Anthropic has released Claude Haiku 5.5, scoring 43 on the Artificial Analysis Intelligence Index - up 26 points one year after the last Haiku releaseHaiku 5.5 is the first Haiku model with Anthropic’s effort settings and adaptive thinking, and Anthropic has introduced tiered pricing.Haiku 5.5 is cheaper than its predecessor - it costs $0.10/$0.50 per 1M input/output tokens for prompts up to 100k tokens (the same as GPT-6 Luna and 10% of the previous Haiku model). However, this pricing rises 5x to $0.50/$2.50 above 100k. The site does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon.Key takeaways:
➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 points
➤ Heavy token use compared to GPT-6 Luna: Haiku 5.5 (max) uses ~162k output tokens per Intelligence Index task, ~3x GPT-6 Luna (max, ~50k). Moving from xhigh to max adds 2 points for ~1.8x the tokens. At similar intelligence it also uses more tokens than GPT-6 Luna: Haiku 5.5 (high) scores 38 with ~55k tokens per task against 38 with ~50k for Luna (max), and the gap widens at lower effort settings➤ Highly capable at agentic knowledge work: on AA-Briefcase, our private evaluation for realistic knowledge work tasks, Haiku 5.5 (max) reaches 1578 Elo, ahead of models including Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 (max)
➤ Improvements on terminal use: on Terminal-Bench 4.0 it scores 33%, up from 0% for Haiku 4.5. This is level with GLM-5.3 Flash, and ahead of Gemini 3.8 Flash (20%) and GPT-6 Luna (13%)
➤ Lower factual knowledge, but relatively low hallucinations: as expected for a smaller-class model, Haiku 5.5 has lower factual knowledge than its siblings. AA-Omniscience accuracy is 36%, against 55% for Gemini 3.8 Flash and 44% for GPT-6 Luna, but this is partly driven by more willingness to admit when it doesn’t know - its hallucination rate is lower, at 40% against 55% and 77%
➤ AutomationBench-AA result likely understated: Haiku 5.5 scores 35%, against 53–60% for GPT-6 Luna, Gemini 3.8 Flash and GLM-5.3 Flash. During pre-release testing, a safety refusal issue caused the model to over-refuse. Anthropic is working on resolving this - we will re-run this evaluation with the fix, and expect this score to riseOther model details:
➤ Context window: 1 million tokens, up from 200k for Claude 4.5 Haiku
➤ Pricing: $0.10/$0.50 per 1M input/output tokens up to 100k tokens, $0.50/$2.50 above. Cache reads $0.01 ($0.05 above 100k), 5 minute cache writes $0.125 ($0.625 above 100k)➤ Multimodality: Text and image input, with text output
We use essential cookies to make this site work, and optional cookies to enhance your experience.